What Is Agentic AI Testing? A Practical Guide for QA Teams
Learn how agentic AI testing plans, executes and adapts tests, how it differs from traditional automation, and where human oversight matters.
Most automated tests are good at following instructions. Give them a defined path, stable test data and reliable selectors, and they will repeat the same checks quickly. The difficulty begins when the path changes.
A new modal interrupts checkout. A requirement introduces another approval step. The expected control moves or appears only for certain users. Traditional automation does not decide what to do next; it follows the logic written into the script and fails when that logic no longer matches the application.
Agentic AI testing takes a different approach. An AI agent receives a testing goal, relevant context and boundaries. It can inspect the application, choose actions, observe the results and adjust its next step.
That does not make the agent responsible for product quality. QA teams still define the risks, expected outcomes and limits. The useful shift is that automation can do more than repeat a path: it can help investigate what happens around it.
What Does “Agentic” Mean in Software Testing?
An AI agent is a system that can work toward a defined goal with a degree of autonomy. It evaluates its current state, chooses from the actions available to it and uses new information to decide what to do next.
In software testing, the goal might be:
Verify that a registered customer can buy an in-stock item using a valid card, receives an order confirmation and cannot accidentally place the order twice.
To pursue that goal, an agent may navigate a workflow, call an API, check responses and record unexpected behaviour. If the application state changes, it can reassess instead of stopping because one predefined step failed.
A practical definition is:
Agentic AI testing is an approach in which AI agents plan and perform testing activities toward a defined quality goal, adapting their actions to application behaviour while operating within human-set controls.
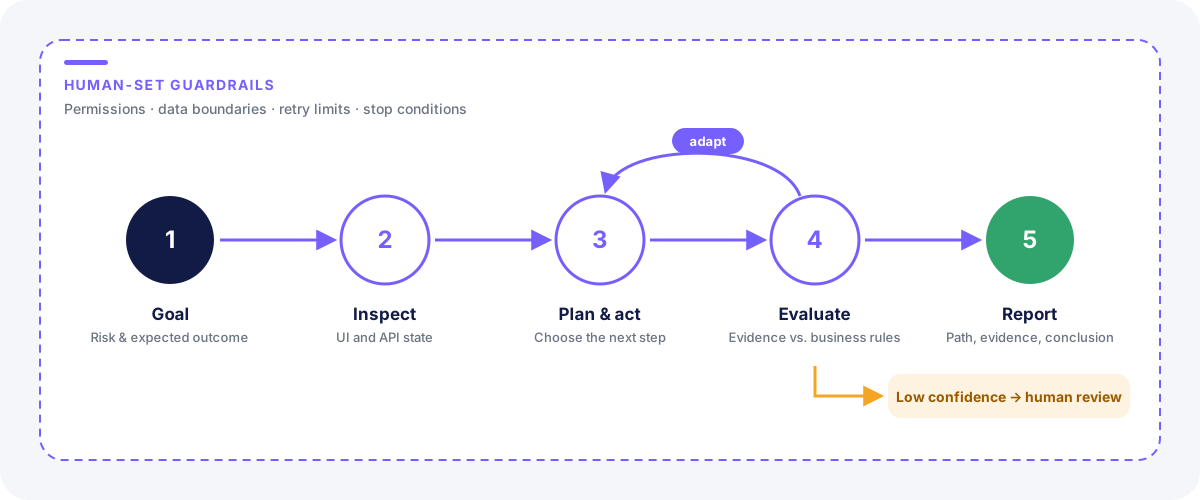
Teams still decide what the agent can access, which actions it can take, what evidence it must collect and when it should stop for review.
How Agentic AI Testing Works
Implementations vary, but a useful agentic workflow usually contains five activities.
1. Understand the Goal
“Test the checkout” is too vague. The agent needs the user role, expected business outcome, acceptance criteria, constraints and known areas of risk. Requirements, Jira stories, BDD files, API specifications and previous execution results can all provide context.
2. Inspect the Application
The agent observes the current interface or API state, identifying controls, screens, endpoints or schemas relevant to its goal.
This is what separates useful exploration from random clicking. The agent needs enough context to choose a sensible next action.
3. Plan and Perform Actions
The agent selects a path that could verify the expected outcome or expose a problem. It acts, observes what happened and continues until it reaches an outcome, a limit or a situation that requires review.
If a modal appears or an element moves, a context-aware agent may reassess the interface rather than fail because a hard-coded selector no longer matches.
4. Evaluate Evidence
Execution alone is not testing. The agent needs a reliable way to judge the result. Evidence may include page state, API responses, business rules, database changes, screenshots, logs and explicit acceptance criteria.
Where the expected result is ambiguous, the right outcome is “needs review”—not a confident pass or failure.
5. Report and Hand Off
The system should record its path, observations, evidence and conclusion. A result is difficult to trust if the team cannot reconstruct the agent’s actions.
Agentic Testing vs. Traditional Automation
Traditional automation remains valuable. It is fast, repeatable and predictable when teams know exactly what they need to validate. Agentic testing adds flexibility where the route to the answer is not fully known in advance.
| Area | Traditional automation | AI-assisted testing | Agentic AI testing |
|---|---|---|---|
| Starting point | Predefined script | Prompt or existing test | Goal, context and constraints |
| Path | Fixed by the author | Usually fixed after generation | Selected and adjusted during execution |
| Response to change | Fails or follows coded recovery | Suggests a repair | Reassesses and continues within limits |
| Exploration | Limited to coded paths | Helps people create more paths | Investigates paths during execution |
| Human role | Designs and maintains scripts | Reviews AI suggestions | Defines goals, evidence and guardrails |
| Best fit | Stable regression checks | Faster authoring and analysis | Dynamic exploration and multi-step workflows |
Teams do not need to choose one and discard the other. Deterministic tests remain the right choice for critical controls that must behave consistently. Agents are useful when broader exploration or adaptation adds meaningful coverage.
A Practical Example: Exploring Checkout Risk
Consider a release that changes promotions, delivery options and payment handling. The existing regression suite covers a standard purchase, an invalid card and an expired discount code.
An agent could receive a broader goal: assess checkout risk for registered customers across eligible basket and delivery conditions. Using approved accounts and a payment sandbox, it might explore what happens when a customer:
- Applies a discount before changing the basket quantity
- Removes an item after selecting delivery
- Returns from payment to edit the address
- Submits an order twice during a slow response
- Combines an out-of-stock item with a promotion
The value is not more clicks. If a quantity change invalidates a discount, the agent can check whether the message, total and checkout eligibility remain consistent.
But more exploration does not guarantee better testing. An agent may complete ten paths and still miss the rule the business cares about most. If nobody explains that a promotion must never reduce a regulated fee, the agent cannot reliably infer that requirement from the screen. The quality of its work still depends on the context and expected outcomes supplied by the team.
Where Agentic Testing Helps—and Where It Needs Oversight
Agentic testing is most useful in workflows with multiple states, roles or conditional branches. It can explore alternative paths, identify candidates for regression coverage and collect evidence for failure investigation.
Human review remains important when:
- Requirements conflict or lack clear acceptance criteria
- Tests touch personal, financial or production data
- An action is destructive or difficult to reverse
- A visual difference may be intentional
- A self-healing decision could hide a genuine regression
- The agent reports low confidence or cannot infer business impact
Non-determinism also needs to be managed. An agent may not choose exactly the same path on every run. Stable regression gates should remain separate from exploratory agent runs, and teams should record the goal, context, actions and evidence from each execution.
How to Evaluate an Agentic Testing Platform
Ask vendors to demonstrate a realistic application change rather than relying on the word “agentic.” Focus on six questions:
- What can the agent decide? Confirm whether it only generates scripts or can observe, plan, execute and adapt.
- What evidence does it provide? Look for screenshots, logs, assertions, execution paths and decision history.
- How are guardrails controlled? Check permissions, data boundaries, retry limits and stopping conditions.
- How does it handle uncertainty? A trustworthy system should flag ambiguity instead of manufacturing confidence.
- Can decisions and changes be reviewed? Generated tests and self-healing actions should be inspectable and reversible.
- Does it work with the existing quality stack? Examine how it operates alongside scripted automation, CI/CD and current reporting workflows.
Measure the platform by the quality of its findings, maintenance effort avoided and time required to investigate failures—not by the number of tests it generates.
How Nogrunt Approaches Agentic AI Testing
Nogrunt connects agentic exploration with the wider quality engineering workflow. Its agents can explore application flows within defined testing goals and controls, while the Browser Agent uses visual interaction to navigate web applications.
The platform also generates tests from requirements and Jira stories, supports API test generation and makes self-healing actions visible for review. Its generated automation code is portable across established frameworks.
The goal is not to remove QA professionals from the process. It is to give them more capacity for risk analysis, exploratory thinking and release decisions while automation handles more of the repetitive discovery and execution work.
Learn more about the Nogrunt Browser Agent, context engineering for reliable AI testing and Nogrunt platform capabilities.
Frequently Asked Questions
How is agentic testing different from generative AI testing?
Generative AI produces outputs such as test cases or scripts. Agentic AI can plan, act through tools, observe results and continue working toward a goal.
Is agentic testing fully autonomous?
It can perform some tasks with limited supervision, but responsible implementations use permissions, stopping conditions and review points. High-risk decisions should remain under human control.
Will agentic AI replace test automation frameworks?
No. Agents still need reliable ways to interact with browsers, APIs and applications. Agentic workflows complement established automation frameworks and deterministic regression suites rather than making them unnecessary.
Will agentic AI replace QA engineers?
Agentic systems can reduce repetitive test creation, execution, and investigation. QA engineers are still needed to define risk, clarify requirements, establish controls, review uncertain findings and decide whether the available evidence supports a release.
A Sensible Place to Start
Do not begin by handing an agent your largest regression suite. Choose one contained workflow with clear business rules, safe test data and a known baseline. Let the agent explore it, then assess whether its findings improve risk coverage or simply create more noise.
Agentic testing earns its place when it helps the team find meaningful risks and understand failures sooner—not simply when it produces more tests.
To see how agents can work alongside your existing web, mobile and API automation, explore the Nogrunt platform or book a demonstration.