Flaky Tests: Why They Happen and How to Fix Them
Learn what causes flaky tests, how to diagnose unreliable automation and when retries or self-healing help - or simply hide the problem.
The build fails. Someone reruns it without changing the code. This time, everything passes.
The immediate problem appears to be gone, but the team has learned nothing. Was there a real regression? Did the test start too early? Did another test change the data? Was the environment temporarily unavailable?
A test that sometimes passes and sometimes fails under the same intended conditions is flaky. Over time, unreliable results change how people treat the suite. Engineers rerun failures instead of investigating them, and genuine defects become easier to dismiss.
Fixing flaky tests starts with identifying the source of uncertainty. A broken selector needs a different remedy from shared test data, an overloaded environment or an incorrect wait. Retries and self-healing can help in specific situations, but neither should become a blanket solution.
What Is a Flaky Test?
A flaky test produces inconsistent results without a relevant change to the application or test. It may pass on one run and fail on the next because its outcome depends on timing, execution order, shared state, infrastructure or another uncontrolled condition.
This differs from a repeatable failure, which usually points to a product defect, an outdated expectation, or a persistent test problem. Flakiness is harder to diagnose because a rerun can make the evidence disappear.
The goal should not be to keep every building green. It should be to make failures meaningful. When a test fails, the team needs enough confidence to treat that result as information rather than noise.
Common Causes of Flaky Tests
| Cause | What it often looks like | Practical response |
|---|---|---|
| Unstable selectors | The test sometimes finds the wrong element or fails after a UI change | Prefer stable roles, labels or test IDs; use controlled self-healing for genuine locator changes |
| Timing and synchronisation | An element, request or background job is not ready when the assertion runs | Wait for a meaningful condition instead of using fixed delays |
| Shared test data | Tests update or delete the same user, order or account | Create isolated data or assign unique records per test |
| Environment instability | Failures cluster around deployments, resource pressure or unavailable services | Monitor environment health and separate infrastructure failures from product results |
| Test-order dependency | A test passes in the suite but fails alone—or the reverse | Give every test its own setup and cleanup; remove reliance on earlier tests |
| Network and API issues | Requests time out or return temporary errors | Capture request details; use mocks only where they preserve the purpose of the test |
| Parallel-execution conflicts | Tests pass sequentially but fail when workers run together | Isolate accounts, files, ports and other shared resources |
| Weak assertions | The test checks before the system reaches the expected state | Use condition-based assertions tied to the real outcome |
The same symptoms can have different causes. A missing checkout button might indicate a changed locator, slow page state, failed API response or insufficient permission. Treating all four selector problems creates the wrong fix.
1. Replace Fixed Waits with Observable Conditions
Timing failures often begin with assumptions such as “the page will be ready in two seconds.” Increasing every timeout makes the suite slower and may only reduce how often the problem appears.
Wait for evidence that the system has reached the required state:
- An element is visible and enabled
- A network request has completed
- A status has changed
- A record appears in the response
- A loading indicator has disappeared
- The expected business result is available
Modern frameworks support condition-based waiting. Cypress, for example, retries linked queries and assertions until they succeed or time out.
2. Isolate Tests and Their Data
A reliable test should control its own state. It should not assume another test created by a user, left an item in a basket or updated an account. Shared accounts cause similar problems when one worker changes data another worker still needs.
Use unique data where possible and establish required state during setup. Browser states should also be isolated. Playwright creates separate browser contexts, so cookies, local storage and sessions do not leak between tests.
3. Make Parallel Execution Safe
A suite that becomes unreliable only in parallel usually depends on a resource incorrectly assumed to be exclusive.
Common examples include:
- Reusing the same account or email address
- Writing to the same file or storage location
- Updating the same database record
- Depending on a shared queue or temporary environment
- Using fixed ports or identical external references
Run suspected tests with different worker counts. If failures appear only under concurrency, look for shared resources before adjusting timeouts. Assign unique data and resource identifiers to each worker.
4. Separate Product Failures from Environment Failures
An overloaded environment, expired credential, unavailable dependency or incomplete deployment can make valid checks fail.
Capture the evidence needed to distinguish these causes:
- Application and service logs
- Network requests and responses
- Screenshots or traces
- Environment version and deployment status
- Test data identifiers
- Worker and retry number
- Timestamps around the failure
“Element not found” is rarely enough evidence. The page may never have received the data required to render it.
When Retries Help—and When They Hide Problems
Retries can collect more evidence or keep one intermittent failure from blocking a diagnostic run.
A retry does not fix the cause. If the first attempt fails and the second passes, the test should still be investigated. Playwright explicitly categorises this result as “flaky.”
Use retries with limits and visibility:
- Record the initial failure and retry result
- Track which tests require retries
- Avoid repeatedly retrying destructive actions
- Do not count “passed after retry” as equivalent to a first-run pass
- Assign frequently retried tests for investigation
Temporary quarantine needs an owner and review date. Otherwise, important coverage can quietly disappear.
Where Self-Healing Is Appropriate
Self-healing is relevant when the application changes, but expected behaviour does not—for example, when a button keeps the same role and purpose after its ID changes.
It cannot fix slow data, failed APIs, incorrect results, or order dependency. Locator healing in those situations treats only a symptom.
A trustworthy workflow records the original locator, replacement, confidence and subsequent assertion result. Low-confidence changes should require review. See What Is Self-Healing Test Automation and How Does It Work?.
How to Measure and Reduce Flakiness
Track flakiness at the individual-test level instead of relying only on the pipeline pass rate.
Useful measures include:
- Tests that pass only after retry
- Flaky failures by cause and component
- First-run pass rate
- Time spent investigating non-product failures
- Tests currently quarantined
- Reopened flakiness issues
- Failures that cannot be reproduced
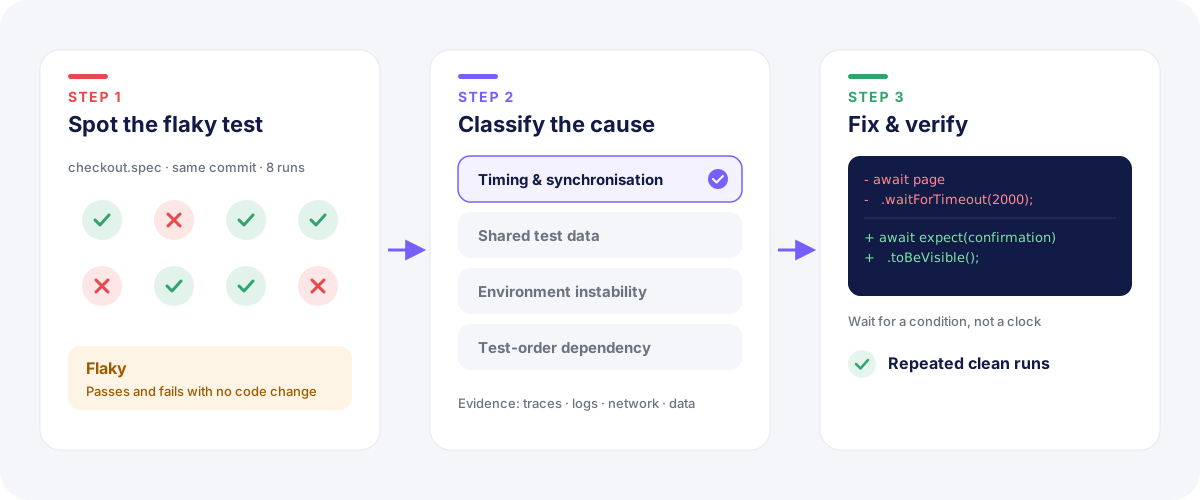
A practical reduction workflow is:
- Identify the tests producing the most unreliable runs.
- Preserve traces, logs, network evidence, and test data from failures.
- Reproduce under different orders, worker counts, and environment conditions.
- Classify the cause before choosing a fix.
- Verify the fix through repeated clean runs and continue monitoring it.
Prioritise tests that protect critical journeys or regularly interrupt delivery. A flaky cosmetic check and an unreliable payment test do not carry the same risk.
How Nogrunt Helps Teams Improve Test Reliability
Nogrunt’s self-healing capability can address recoverable UI changes while keeping actions visible for review. Its failure-analysis capabilities help teams examine execution evidence rather than relying on a one-line message. Parallel execution and delivery integrations keep results connected to the wider quality process.
The objective is not to turn unreliable tests green. It is to reduce maintenance noise without weakening the suite’s ability to expose genuine defects.
Learn more about Nogrunt platform capabilities, self-healing test automation and agentic AI testing.
Frequently Asked Questions
What is a flaky test?
A flaky test passes and fails inconsistently even though the relevant application behaviour and test conditions are intended to remain the same. Timing, shared state, environment instability and test dependencies are common causes.
Should flaky tests be retried automatically?
Limited retries can collect evidence and prevent one intermittent failure from stopping a diagnostic run. A test that passes after retry should still be marked as flaky and investigated.
Can self-healing fix flaky tests?
Only some of them. Self-healing can help when a genuine UI or locator change breaks an otherwise valid test. It will not fix unstable data, timing errors, failed dependencies or poor isolation.
Should a flaky test be deleted?
Not automatically. First determine what risk the test covers and why it is unreliable. Repair it where possible; quarantine it temporarily when necessary, with an owner and deadline. Remove it only when the scenario no longer provides useful coverage.
Make Every Failure Worth Investigating
Flaky tests are not just an automation inconvenience. They weaken the feedback loop that teams depend on to make release decisions.
Start with the tests that fail most often or protect the highest-risk journeys. Capture enough evidence to classify each failure, fix the source of uncertainty and verify the result across repeated runs.
A reliable suite does not need to pass all the time. It needs to fail for reasons the team can trust.
To learn how Nogrunt helps teams reduce automation maintenance while preserving meaningful failure signals, explore the Nogrunt platform or book a demonstration.